120 Tokens/s of DeepSeek R1 32B on a Desk? TFNEW ZH-G3
TL;DR: TFNEW launched the ZH-G3, an enterprise AIPC all-in-one device, on September 21, 2026. Shipped as a DeepSeek R1 32B edition, it delivers 120 tokens/s (FP16) with 142 TFLOPS of total compute and a 24 GB video-memory pool — a self-contained 8 kg box that runs a 32B-class reasoning model on-site for up to 10 people, no rack, no GPU cluster. Get specs and pricing: sales@tfnew.com.
Core Specifications (with Plain-Language Terms)
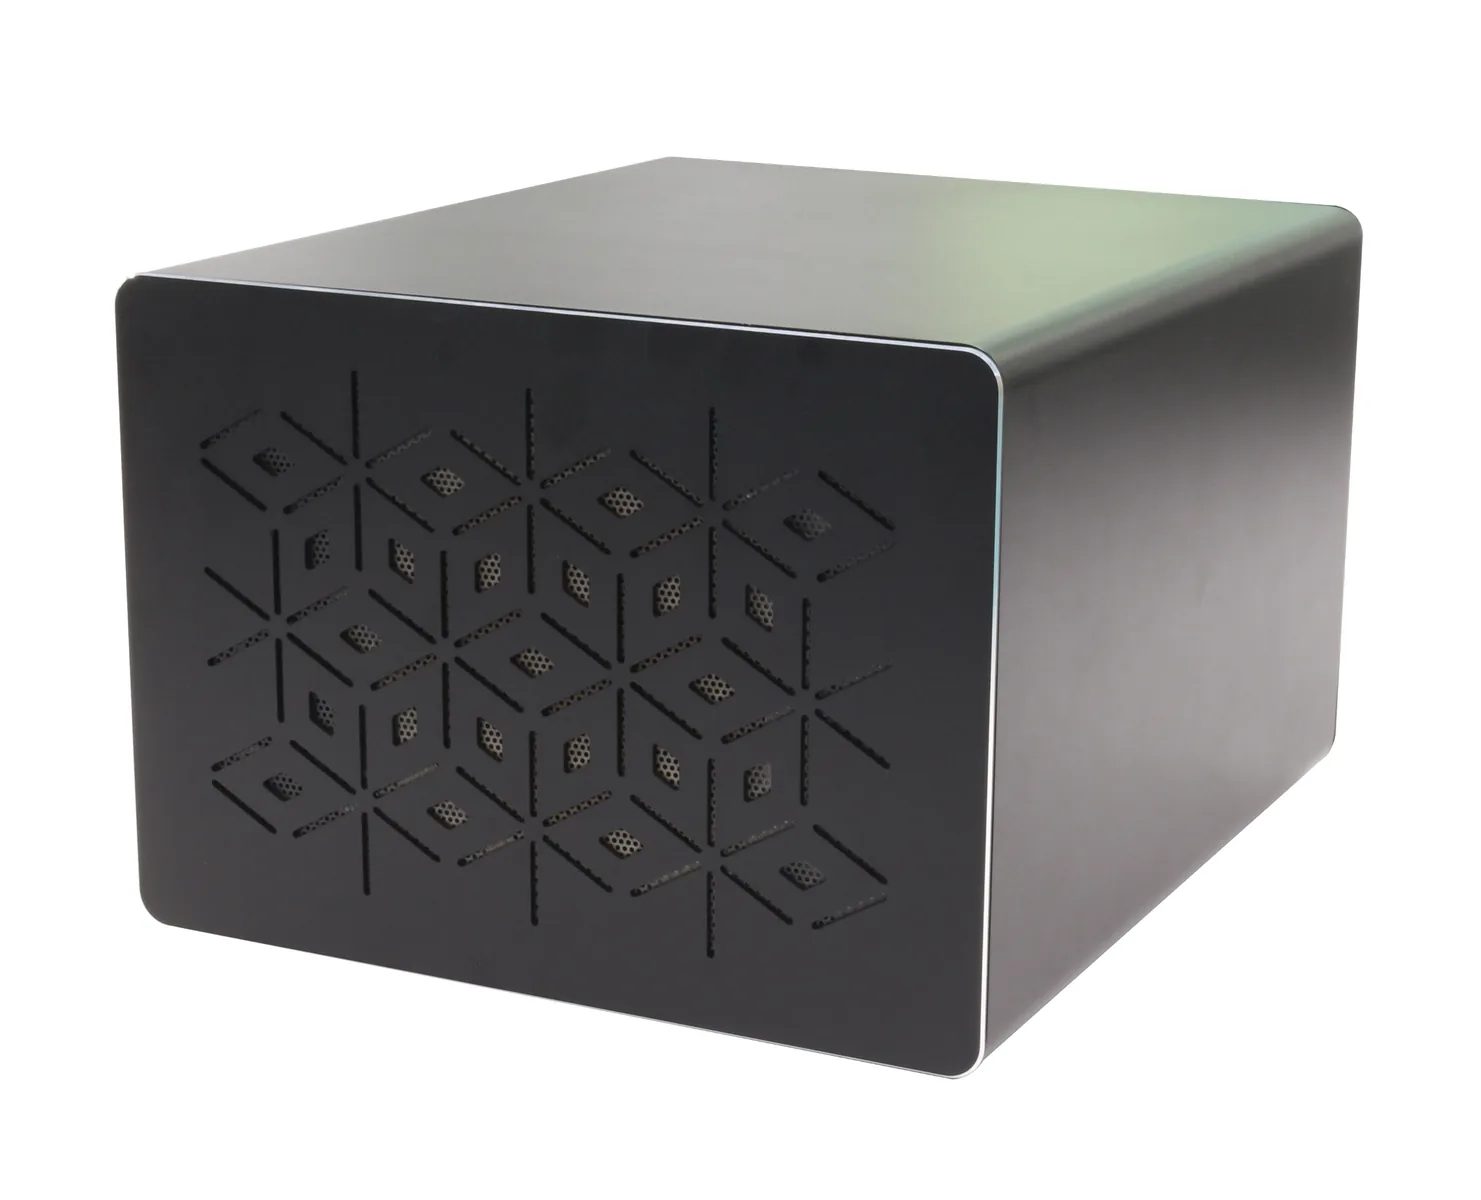
The ZH-G3 is an "AIPC" — an AI personal computer, but this one is designed for enterprises: an all-in-one appliance that ships with DeepSeek R1 32B pre-integrated. "32B" refers to the model's scale — roughly 32 billion parameters — and R1 is DeepSeek's reasoning model family, which generates visible chain-of-thought before answering. Token throughput is the spec that matters: 120 tokens/s at FP16 precision (uniform, full-precision inference rather than quantization tricks), enough for interactive chat and analysis work. The device supports 4 concurrent requests and can sustain an estimated 8,640,000 tokens per day, sized for up to 10 recommended users. Total compute is 142 TFLOPS (FP16) with a 24 GB video-memory pool. It pulls 700 W at full load from standard AC (100–264 V), weighs 8 kg, and measures 200.5 × 280 × 330 mm — a desk-side box, not a rack unit.
Specs at a Glance
| Item | ZH-G3 Value |
|---|---|
| Model edition | DeepSeek R1 32B |
| Performance | 120 tokens/s (FP16) |
| Concurrency | 4 concurrent requests |
| Throughput | ~8,640,000 tokens/day (24 h) |
| Users | Up to 10 recommended |
| Compute | 142 TFLOPS (FP16), 24 GB video-memory pool |
| Power | 700 W full load, AC 100–264 V |
| Weight / Size | 8 kg; 200.5 H × 280 W × 330 D mm |
| Network | 1x 1000M port |
| Environment | 0°C–40°C operating range |
Why an On-Site 32B Appliance Changes the AI Conversation
Sending data to a cloud LLM means sending data. The ZH-G3's argument is the opposite: a 32B-class reasoning model, installed and running in the room, at conversational speed — 120 tokens/s FP16, four concurrent requests, ten users. For teams with confidential documents, compliance constraints or offices without cloud connectivity, this is the appliance tier between a laptop and a GPU rack: dedicated compute (142 TFLOPS), a 24 GB memory pool, 700 W from a wall outlet and zero GPUs to provision. One port, one power cable, one model — out of the box.
Where It Fits
- Confidential/regulated teams: R1 32B inference entirely on-site
- Small workgroups: up to 10 users sharing one appliance
- Remote sites without cloud: self-contained model access over a LAN link
- Evaluation and prototyping: a fixed-cost unit for agent and RAG pilots
Why the Numbers Matter
- 120 tokens/s FP16: full-precision throughput at chat-interactive speed
- 142 TFLOPS (FP16): dedicated local compute, not cloud burst
- 24 GB video-memory pool: the resident memory of a 32B model at precision
- 4 concurrent requests / 10 users: appliance-class concurrency out of the box
- 700 W, 8 kg: rack-free, wall-plug AI for the office
What TF NEW Says
"Cloud LLMs answer your questions and keep your logs — that's the trade-off the ZH-G3 removes," said a TF NEW product manager. "It's DeepSeek R1 32B, 120 tokens/s at FP16, fourteen-plus TFLOPS and a 24 GB pool, all in an 8 kg box that runs from a wall outlet. Ten users, one appliance, zero data egress. That's enterprise AI you can point at."
Quality and Availability
Every ZH-G3 ships factory-integrated and validated for the 32B delivery profile — token throughput, concurrency and thermals verified at 100% load in the 0°C–40°C envelope. Contact sales@tfnew.com for the model edition and deployment guidance.
Pricing and Availability
The ZH-G3 is available now. Pricing varies by software edition and support options. Contact sales@tfnew.com or use the request-a-quote form at www.tfnew.com/contact for configuration guidance and lead time.
About TF NEW
TF NEW (TF New Technology) is an enterprise AI infrastructure provider based at www.tfnew.com. It designs and delivers private AI, compute, networking, storage, cooling and edge systems as deployment-ready solutions — AI servers, AI workstations, edge AI, liquid cooling and enterprise rack servers — for AI factories, datacenters and edge projects worldwide.
Media Contact
TF NEW | sales@tfnew.com | www.tfnew.com/contact
FAQ
- What is the ZH-G3? An enterprise AIPC all-in-one that ships with DeepSeek R1 32B pre-integrated.
- How fast is it? 120 tokens/s at FP16, with 4 concurrent requests.
- How many users can share it? Up to 10 recommended, with ~8.64M tokens/day throughput.
- What hardware is inside? 142 TFLOPS (FP16) total compute and a 24 GB video-memory pool, 700 W at full load.
- Does it need a rack or cloud? No — an 8 kg desk-side appliance with one 1000M network port.