Ten GPUs, Each on Its Own x16? TFNEW ZH-5201
TL;DR: TFNEW launched the ZH-5201, a 5U 10-GPU passthrough server, on September 21, 2026. On 2x 4th/5th Gen Intel Xeon Scalable with 32 DDR5 slots, its passthrough GPU backplane gives each of up to ten 600 W accelerators a dedicated x16 lane set — no switch chip in the path — for large-model training and inference where deterministic per-GPU bandwidth is the point. Get specs and pricing: sales@tfnew.com.
Core Specifications (with Plain-Language Terms)
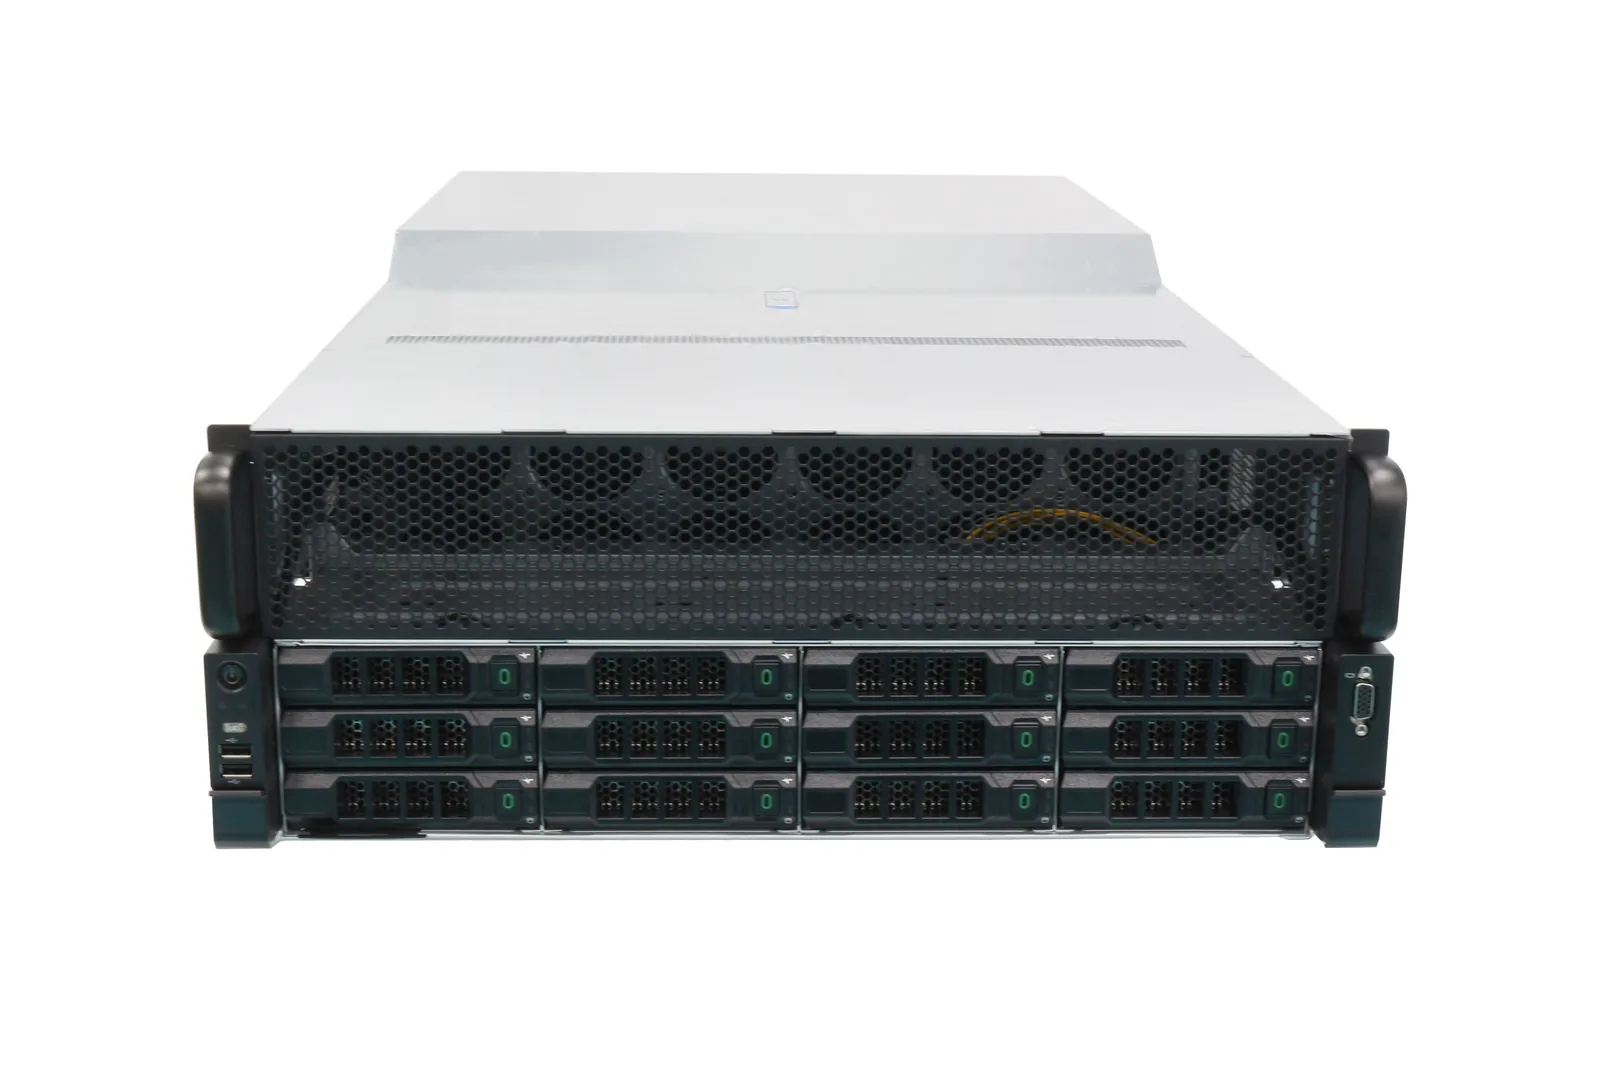
The ZH-5201 is the passthrough configuration of TF NEW's 5U GPU platform: no PCIe switch, no fan-out — each accelerator connects straight to its own set of x16 lanes via a passthrough GPU backplane supporting 12 standard x16 slots and up to ten full-height full-length dual-width cards at 600 W TDP each. "Passthrough" means the PCIe topology is direct: GPU lanes go from CPU/bridge roots to the card without an intermediate chip, so bandwidth per GPU is fixed and predictable rather than shared. Around it: two 4th/5th Gen Intel Xeon Scalable processors on an Intel C741 chipset with 32 DDR5 slots (4400/4800/5600 MHz), twelve 3.5-inch bays, 4x CRPS supplies in 3+1 redundancy (2000 W/2700 W), ten high-performance fans, one management port plus an OCP 3.0 interface, and a DC-SCM 2.0 management module with AST2600 BMC (IPMI 2.0 / Redfish).
Specs at a Glance
| Item | ZH-5201 Value |
|---|---|
| Form factor | 5U rackmount GPU server |
| Processor | 2x 4th/5th Gen Intel Xeon Scalable, Intel C741 |
| Memory | 32x DDR5 slots, 4400/4800/5600 MHz |
| GPU | Up to 10x 600 W full-height full-length dual-width cards |
| PCIe | Passthrough GPU backplane, 12x x16 standard slots |
| Storage | 12x 3.5" bays (2.5" compatible) |
| Power | 4x CRPS hot-swap, 3+1 redundant, 2000 W / 2700 W |
| Cooling | 10 high-performance fans |
| Management | DC-SCM 2.0, AST2600 BMC, IPMI 2.0 / Redfish |
| Network | 1x management port, 1x OCP 3.0 |
Why Passthrough Is the Training Choice
Switch topologies multiply slot counts; passthrough topologies protect bandwidth. For large-model training and inference, the failure mode of dense GPU servers is variable per-GPU throughput — one card starving on shared lanes during a collective operation. The ZH-5201's passthrough backplane removes that variable: ten cards, each with a dedicated lane path, so data-parallel and tensor-parallel jobs see consistent bandwidth job after job. Teams that know they will provision ten cards and want zero ambiguity about the fabric choose passthrough — that is what the ZH-5201 sells.
Where It Fits
- Large-model training: deterministic per-GPU bandwidth for data/tensor-parallel runs
- Large-model inference: fixed fabric performance for serving fleets
- 8–10 GPU single-node builds: one box, predictable lanes, 600 W cards
- Fleet standardization: same passthrough topology node after node
Why the Numbers Matter
- 10x 600 W GPUs with dedicated x16 lanes: predictable per-card bandwidth
- 32x DDR5 up to 5600 MHz: weights and activations resident per node
- Passthrough backplane, 12x x16: no switch chip in the data path
- 3+1 CRPS redundancy: power that survives a supply failure
- DC-SCM 2.0 + OCP 3.0: serviceable management and modern NIC interface
What TF NEW Says
"More lanes per card is not a spec-sheet fetish — it's training stability," said a TF NEW product manager. "The ZH-5201 gives each of ten 600 W GPUs its own passthrough x16 path, which means the fabric isn't a variable in reproducibility. For large-model teams that will actually run all ten cards, that determinism is the product."
Quality and Availability
Every ZH-5201 runs 48 hours of burn-in testing under full GPU load before shipping, with all passthrough lane paths and power feeds validated in the factory. It ships deployment-ready with DC-SCM 2.0 baselines and a documented GPU compatibility matrix.
Pricing and Availability
The ZH-5201 is available now. Pricing varies with processor, memory, GPU and power configuration. Contact sales@tfnew.com or use the request-a-quote form at www.tfnew.com/contact for configuration guidance and lead time.
About TF NEW
TF NEW (TF New Technology) is an enterprise AI infrastructure provider based at www.tfnew.com. It designs and delivers private AI, compute, networking, storage, cooling and edge systems as deployment-ready solutions — AI servers, AI workstations, edge AI, liquid cooling and enterprise rack servers — for AI factories, datacenters and edge projects worldwide.
Media Contact
TF NEW | sales@tfnew.com | www.tfnew.com/contact
FAQ
- What is a passthrough GPU server? GPUs connect to dedicated lane paths without a PCIe switch, giving each card fixed, predictable bandwidth.
- How many GPUs can the ZH-5201 hold? Up to ten 600 W full-height full-length dual-width accelerators.
- What processors and memory does it use? 2x 4th/5th Gen Intel Xeon Scalable with 32 DDR5 slots up to 5600 MHz.
- What power redundancy does it offer? 4x CRPS supplies in 3+1 configuration, 2000 W or 2700 W.
- Why choose passthrough over Switch? Deterministic per-GPU bandwidth for training and inference, with no intermediate switching chip in the data path.