How Many TOPS per Watt? TFNEW Atlas300IPro
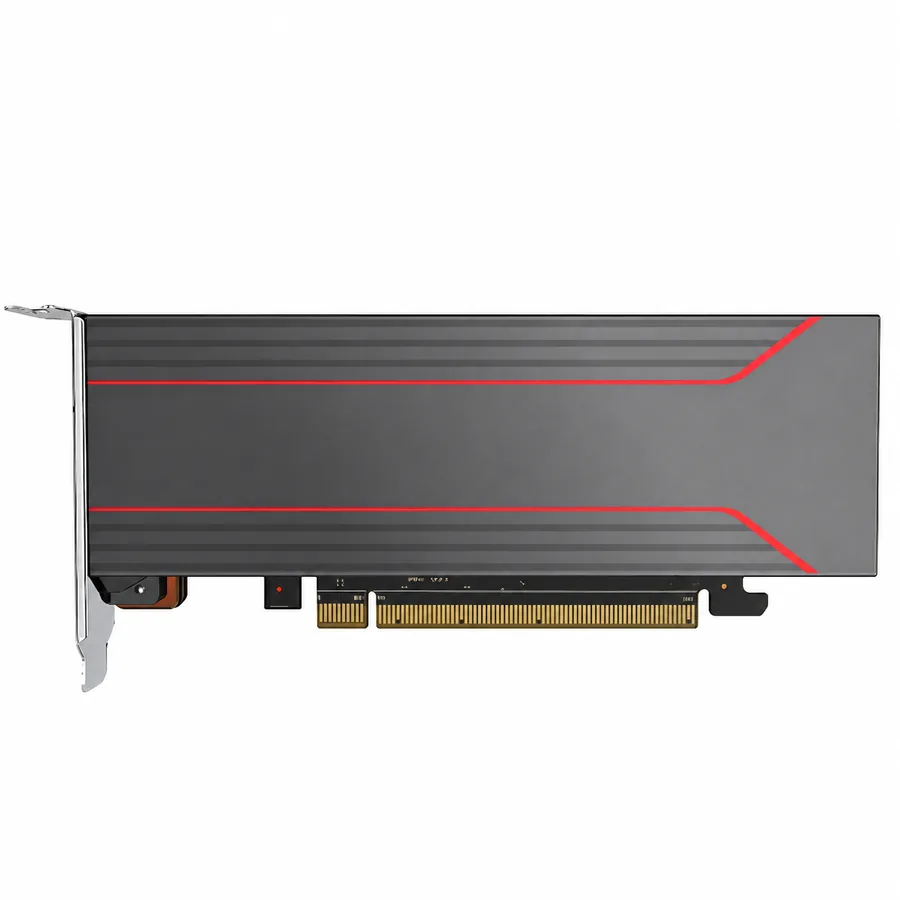
TL;DR: TFNEW launched the Atlas300IPro, a half-height AI inference card, on September 19, 2026. Powered by the Ascend 710 chip, it delivers 140 TOPS (INT8) and 70 TFLOPS (FP16) at up to 72 W — about 2 TOPS per watt — with 24 GB LPDDR4X memory at 204.8 GB/s. It targets OCR, speech recognition, search ranking and content moderation. Get specs and pricing: sales@tfnew.com.
Core Specifications (with Plain-Language Terms)
TOPS (tera operations per second) measures how many trillion operations a card can run per second in INT8 — the format most production AI models are quantized to. 140 TOPS is enough for many concurrent OCR and speech jobs on one card. FP16 (70 TFLOPS) covers mixed-precision inference. The card uses 24 GB LPDDR4X memory with 204.8 GB/s bandwidth, an on-card 8-core 1.9 GHz CPU for preprocessing, and H.264/H.265 video codec for decode/encode. It draws up to 72 W from a PCIe x16 Gen4 slot, so no extra power cabling is needed.
Specs at a Glance
| Item | Atlas300IPro Value |
|---|---|
| Form factor | Half-height, half-length PCIe card |
| AI chip | Ascend 710, secure boot |
| INT8 compute | 140 TOPS |
| FP16 compute | 70 TFLOPS |
| Energy efficiency | ≈2 TOPS/W |
| Memory | 24 GB LPDDR4X, 204.8 GB/s |
| On-card CPU | 8 cores @ 1.9 GHz |
| Codec | H.264/H.265, JPEG |
| Interface / power | PCIe x16 Gen4, up to 72 W |
| Operating range | 0°C–55°C |
INT8 vs FP16: Which Mode to Use
| Item | INT8 | FP16 |
|---|---|---|
| Throughput | 140 TOPS | 70 TFLOPS |
| Typical use | Quantized models, video analytics | Mixed-precision inference |
| Power | Up to 72 W | Up to 72 W |
| Memory | 24 GB LPDDR4X (204.8 GB/s) | 24 GB LPDDR4X (204.8 GB/s) |
INT8 gives roughly 2x the throughput of FP16 on the same silicon, which is why production pipelines usually quantize models before deployment.
Why the Numbers Matter
Power per card (72 W) is the number that decides how many cards fit in a server: ten 300 W GPU cards need heavy power and cooling, while ten 72 W inference cards run off PCIe slots alone. At 2 TOPS/W, a fleet of Atlas300IPro cards can scale inference capacity without upgrading server power or rack cooling. 204.8 GB/s memory bandwidth and the on-card codec keep the bottleneck off the PCIe bus for video-heavy jobs.
Where the Atlas300IPro Fits
- OCR: document digitization and invoice/receipt processing
- Speech recognition: ASR and voice command pipelines
- Search ranking: low-latency reranking and embedding
- Content moderation: image/video filtering at scale
What TF NEW Says
"Inference cost is a power bill, not a chip bill," said a TF NEW product manager. "At 72 W per card, the Atlas300IPro lets operators add 140 TOPS of INT8 capacity without touching their server power budget. That changes how much inference you can afford to run."
Pricing and Availability
The Atlas300IPro is available now. Pricing varies with quantity and firmware options. Contact sales@tfnew.com or use the request-a-quote form at www.tfnew.com/contact for volume pricing and lead time.
About TF NEW
TF NEW (TF New Technology) is an enterprise AI infrastructure provider based at www.tfnew.com. It designs and delivers private AI, compute, networking, storage, cooling and edge systems as deployment-ready solutions — AI servers, AI workstations, edge AI, liquid cooling and enterprise rack servers — for AI factories, datacenters and edge projects worldwide.
Media Contact
TF NEW | sales@tfnew.com | www.tfnew.com/contact
FAQ
- How many TOPS does the Atlas300IPro deliver? 140 TOPS INT8 and 70 TFLOPS FP16.
- What is its power draw? Up to 72 W, powered from the PCIe x16 Gen4 slot.
- What memory does it have? 24 GB LPDDR4X at 204.8 GB/s bandwidth.
- Which workloads is it built for? OCR, speech recognition, search ranking and content moderation.
- Does it do video codec? Yes — H.264/H.265 encode/decode and JPEG encode/decode.